Your Asset Data Is Not Wrong. It’s Just Seven Shades of Right: ISO 14224
Inside the asset taxonomy behind the Rosetta Stone — what ISO 14224, ISO 19650, NIST, and ASTM each contribute to naming equipment, and the two years spent sewing four standards into one structure. No witchcraft required.
Nomina si nescis, perit et cognitio rerum.
If you do not know the names, the knowledge of things is lost as well. — Isidore of Seville, quoted by Linnaeus in Critica Botanica, 1737
In June, we published The Rosetta Stone for Asset Data, which made the case that a maintenance record has to be readable across every system, every role, and every audit.
That piece answered who needs the translation and why the burden lands on the customer when a platform refuses to take it.
This one starts with ISO 14224: a reliability and maintenance data standard first written for petroleum, petrochemical, and natural gas operations that separates asset identity from location and lets equipment class determine the attributes that belong on the record.
For large facility operators (grocery chains, commercial real estate teams, data center operators, and anyone carrying ESG or regulatory reporting obligations across refrigeration and HVAC systems), that distinction is what turns asset data into something consistent, defensible, and usable.
Twenty-five years of field work, ISO 14224 and ISO 19650, and a few turns owning an asset hierarchy myself. Those are standards, not lottery numbers — though after enough years staring at them, I’ve been tempted.
Start with the thing everyone gets backwards. When you go to verify what is in your buildings (an audit, a compliance filing, a CMMS migration), the records rarely turn out to be wrong.
They turn out to be right in several incompatible ways at once. The senior tech knows what to call it.
The regional manager has a system. The last CMMS administrator had a convention nobody wrote down. Every one of them is defensible, and none of them match. That is a harder problem than bad data, because there is nothing to correct.
It also explains why naming an asset still feels like witchcraft in most organizations. There is no magic in the fix. There is a structure built from ISO 14224 and related standards, including ISO 19650, NIST, and ASTM, then applied to taxonomy, hierarchy, HVAC/R classification, adaptive attribute sets, AI-ready labeling, and compliance reporting.
The payoff is not academic: faster tagging, fewer naming collisions, cleaner audits, and asset records that hold up across systems without manual translation.
It is built from published standards, it took two years to assemble, and it is measurably faster than guessing.
Why is establishing an asset naming convention so hard when everyone means well?
Say the word rack on a job site, and you have not yet said anything.
In a warehouse it is steel and bolts, rated in pounds, inspected after every forklift strike. In a supermarket machine room it is compressors, a suction header, and several hundred pounds of refrigerant carrying a legal obligation. In a data center it is nineteen inches wide and measured in U.
Three trades, three inspection regimes, three consequences for getting it wrong. One word, and nobody made a mistake.
That is not a vocabulary problem. Each trade named the thing correctly for the work it does, and the naming diverged because the purposes diverged. An asset taxonomy is not a list of approved words.
It is a purpose, written down, with words attached — and change the purpose and the correct cut moves.
Which is why this cannot be fixed by convening a committee or declaring a winner. There is no wrong party to correct. It can only be resolved once, at the moment of capture, in front of the machine.
📱 Download Tag Wizard
Where do ISO 14224 and ISO 19650 fit?
The June piece argued that structural responsibility never disappears — it only moves. A configurable CMMS hands it to you. NIST’s Nestor puts it in the framework. Tag Wizard absorbs it at capture.
But absorbing a burden is only defensible if you have somewhere to put it. Rigidity you invented is just another person’s opinion, imposed harder. So where did the opinions come from?
Two of them come from ISO, and neither arrived late. ISO 14224 and ISO 19650 were among the data sets we tracked from the first day of this work — and they had been shaping how I thought about equipment classification for decades before that.
Not as a compliance target. As the search for a common denominator that every language in a building could reduce to.
ISO 14224 is the reliability and maintenance data standard written for petroleum, petrochemical, and natural gas operations, originating in the oil and gas industry and widely applied across the gas industry.
Two of its ideas survive the trip into a supermarket machine room intact. It also includes standardized failure modes and causes for equipment, though what matters here is its structural logic for identification.
The first is that where an asset sits and what an asset is are separate questions, and answering them in the same field is what breaks an asset hierarchy the first time equipment moves. That is the standard behind our refusal to encode a store number, a floor, or a room into an asset’s identity. A condenser is a condenser on a roof in Florida or in a rack in Missouri.
Move it, and the record survives the move.
The second is that the equipment class determines the data collected. Know what the thing is, and you know which attributes are relevant — and which are not. That is the standard behind responsive attributes, below.
ISO 19650 is the information management standard for the built environment, grown out of the UK’s BS 1192 and PAS 1192 work. It contributes two more.
The first is level of information need: define what you need, and why, before you collect it — then deliver no more detail than the purpose requires. That is the standard behind stopping at the deepest level the evidence supports.
The second is that information carries its own status. A proposed value and a confirmed value are never the same object. That is the standard behind Wizzy suggesting rather than deciding, behind Apply being a deliberate tap, and behind the suggestion history staying attached to the record as provenance.
There is a third standard worth naming here, because it is the one facility and reliability leaders are most often measured against. ISO 55000 sets out what an asset management system requires, including defined information requirements. It tells you that you need them. ISO 14224 and ISO 19650 are how you satisfy that at the level of a single record.
How do four standards become one structure?
NIST and ASTM were already in the June piece. What was missing was that four standards, written in four rooms, each answer a different question about the same asset — and a record is only defensible once all four have been answered, with structured data analysis across standards.
| Standard | The question it answers | Where it lands in the record |
|---|---|---|
| ISO 14224 | What is this thing, independent of where it sits? | Identity separated from location; the class activates the attribute set and supports operational control when identity and data requirements stay aligned |
| ASTM E3257 | What are its innate characteristics? | Classified by what the equipment is, not what this site happens to use it for |
| NIST — Nestor at the language layer, traceability at the measurement layer | Does the wording resolve, and is the number anchored? | Canonical naming that maps variants to one term; measurements tied to a calibration chain |
| ISO 19650 | What do we need to know, and how sure are we? | Information need defined before capture; status travels with every value |
Read down the right-hand column and the dependency is plain. Identity without traceability is a name with no anchor. A four-pound recovery weight taken on a calibrated scale and a four-pound recovery weight taken on an uncalibrated one are the same number and not the same fact.
Traceability without method is a measurement nobody can compare across two sites. And method without a defined information need is data somebody collected because the form asked for it.
You need all four. None of the four bodies was ever going to sew them together, because none of them had that job.
That is where two years went. Not writing a standard — reconciling four that were never designed to meet.
We adapt these standards. We do not claim compliance with them.
ISO 14224’s equipment classes were built for offshore platforms, and its failure taxonomy is a reliability instrument, not an identification one. ISO 19650’s containers are documents and models; its participants are appointing parties and delivery teams.
Neither was written for someone standing in a mechanical room with a phone and a sun-faded nameplate. We took the principles. The classes, the failure codes, and the document-control machinery stay where they belong.
What is a four-part asset taxonomy?
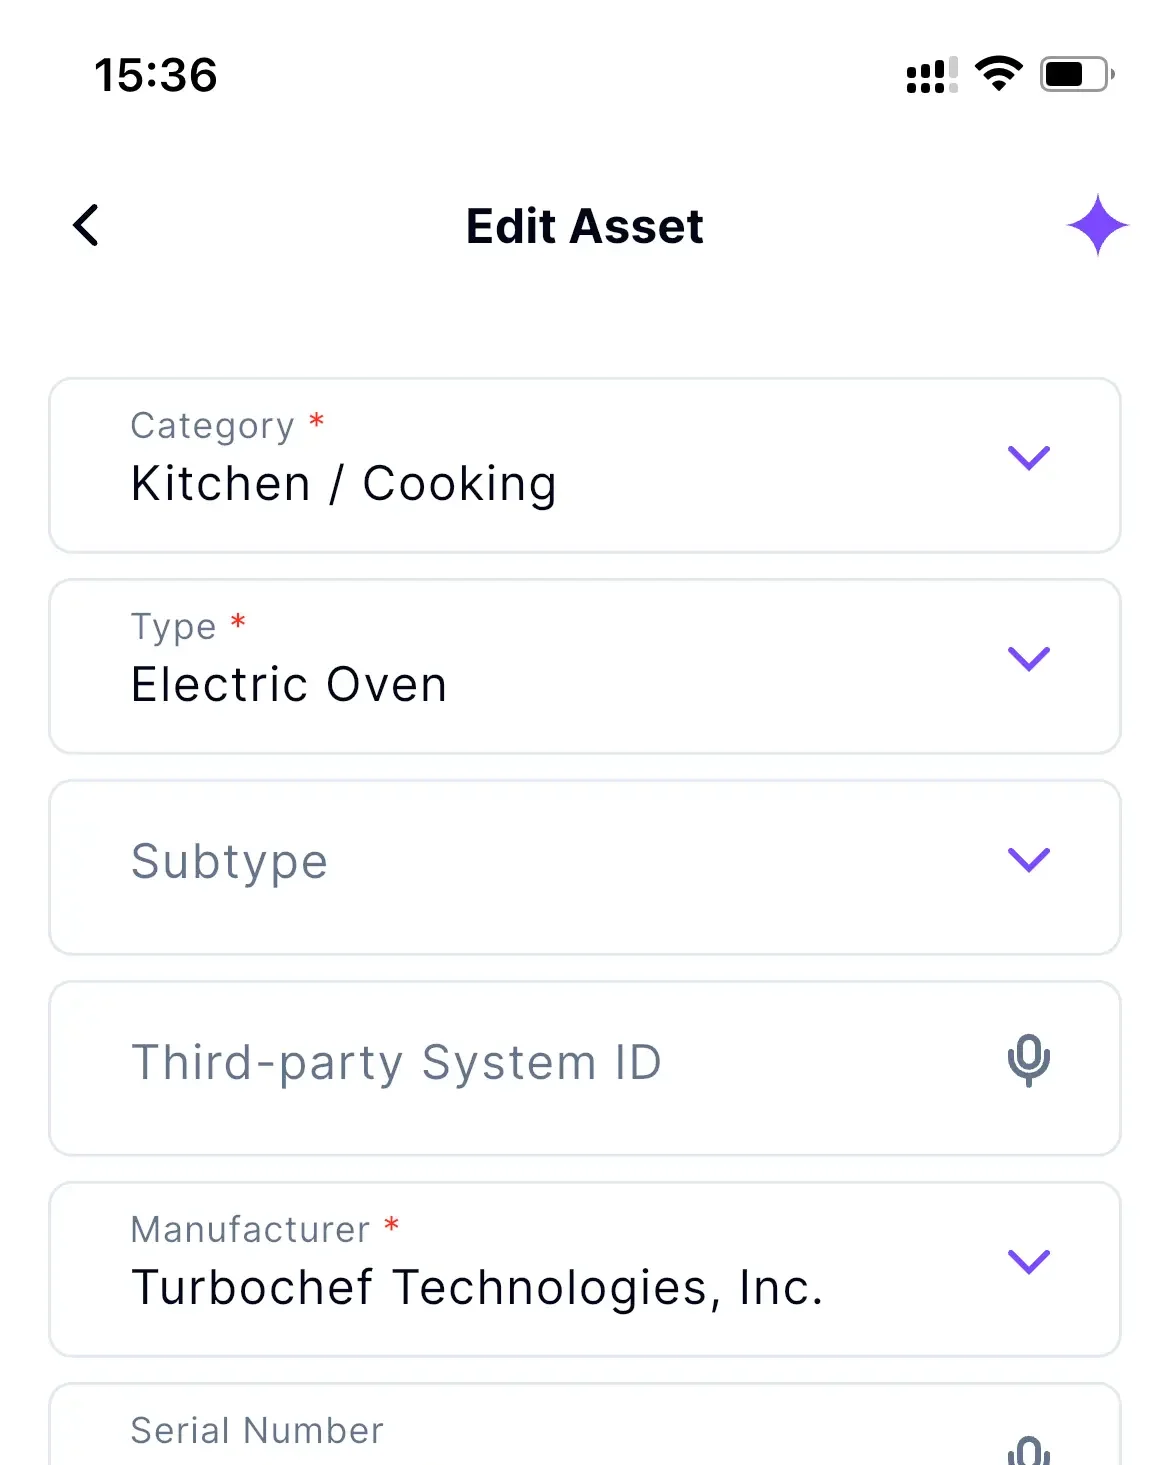
Category, Type, Subtype, Kind.
- Category is the operational family — HVAC/R, electrical, material handling, IT. A good asset hierarchy commonly uses 4-5 levels of organization; this model uses four.
- Type narrows to a recognized equipment group inside it.
- Subtype adds the specific equipment classification.
- Kind carries the most precise designation the evidence actually supports.
Four levels, and the discipline is in how the path terminates. A structured asset hierarchy improves maintenance efficiency and decision-making. It stops at the deepest level the evidence supports, not the deepest level that exists.
Kind not determinable from this image is a complete and defensible answer — and for anyone whose records may be examined later, a far better one than a filled field with nothing behind it.
These levels also establish parent-child relationships, with higher-level equipment above more specific components and child assets.
Why should attributes adapt to the asset?
Naming is only half of an identity. The other half is what you ask: the right asset details for the asset type in front of you.
A fixed attribute set is a taxonomy in disguise. It never announces itself as one, but hand someone a form built for a condensing unit and point them at an evaporator, and the form has already made a claim about what that machine is. They are not merely answering irrelevant questions. They are being asked to certify a description that does not fit.
So the attribute set adapts. Selecting the classification activates the attributes that belong to it, so the record can reflect asset condition, usage history, and maintenance history only where they are actually relevant. The evaporator is never asked for refrigerant type — not hidden, not greyed out. It was never that asset’s question.
| Category | Type | Subtype | Kind | |
|---|---|---|---|---|
| What it answers | What family? | What equipment group? | What specific classification? | What is the most precise designation the evidence supports? |
| Which standard it serves | ISO 14224 — identity separate from location | ASTM E3257 — classified by innate characteristics | ASTM E3257 — the specific class | ISO 19650 — level of information need; stop where evidence stops |
| Supermarket rooftop | HVAC/R | Air conditioning | Packaged unit | Rooftop unit |
| Warehouse floor | Material handling | Lift equipment | Powered pallet truck | Walk-behind |
| Data center | IT infrastructure | Compute | Rack-mount server | 2U |
The set also flexes on evidence while staying anchored to Category and Type.
A gas-assist packaged rooftop takes the HVAC attributes and does not get distracted.
The gas train is real, observed, and recorded in notes — but it does not get to reclassify the machine. A weaker system sees a gas train and starts renaming things.
What does a blank field mean in your asset register right now?
A blank refrigerant field on an evaporator means not applicable. A blank refrigerant field on a condensing unit means we did not capture it.
Same blank, opposite meanings — and a fixed schema erases the difference permanently. Nobody downstream can reconstruct it: not the reviewer, not the CMMS, not the auditor asking why a charge was never recorded.
Fields an asset does not have are never presented, so their absence is unambiguous. Fields it does have and did not get are visibly incomplete.
This is also why adding fields to satisfy more stakeholders never works. It does not solve the problem. It just makes the form longer and weakens maintenance records by forcing irrelevant fields onto the wrong machine.
What happens when the structure does the work?
Where this comes from:
Two organizations with no connection to each other (one in the central and western US, one in the southeast) each measured against its own prior six-month tagging effort. Neither used specialized asset experts, HVAC technicians, or data-center-trained asset managers.
Capable people, low-tech backgrounds, none of whom had tagged an asset before, working across cash registers, hand trucks, lift equipment, retail stock, data center hardware, and refrigeration.
Both came back at roughly eleven times their own prior pace. We will publish the full results jointly at several trade events once we reach the twelve-month milestone. We are sharing the structure now, as we leave the test environment and begin commercializing the app, so others can join the process while it is still open.
Two things in that are worth more than the multiple.
The first is that nothing was shared between the two groups except the structure, which helped enforce consistency across existing assets and new assets. Different organizations, different regions, different asset populations, different people. When two independent groups with nothing in common land in the same place, the structure is the only variable left standing.
The second is who did the work. Not experts. If an expert goes eleven times faster, the tool helped an expert.
When people who had never tagged an asset go eleven times faster across equipment they had never seen (a point-of-sale terminal, a hand truck, a walk-in condenser), the knowledge has moved out of the person and into the taxonomy.
Assets were uniquely identified with a unique identification number so teams were not losing track of inventory assets or creating duplicate records. That is the whole argument, demonstrated rather than asserted.
It also shows the structure is not an HVAC/R structure. It never was. ISO 14224’s principle (the class determines the data) is class-agnostic by design, which is exactly why it holds on a cash register, improving operational efficiency and resource allocation for maintenance teams and the maintenance department.
Tag Wizard ✨ You take one picture. We do the rest.
Why does AI need this more than people do?
A model trained on the industry’s writing has absorbed every one of those naming traditions at once. It can produce any of them fluently, and it has no purpose of its own to choose between them.
So the choice falls to whatever is nearest at hand — the angle of the photograph, the wording on the plate, the phrasing of the prompt, the version of the model. Several legitimate answers, selected at random. That is not hallucination. The model is not inventing anything. It is repeating a real disagreement the industry never resolved, and repeating it inconsistently.
The same thing happens with values. A form creates pressure to fill. Point a model at ten fixed fields, and it will produce ten values, because the schema asked. Remove the fields the asset does not have, and the pressure to fabricate goes with them.
Guardrails supply the missing intent. Ours declare a purpose — identify what this is, from what can actually be seen, well enough to be defended later — and that purpose is what makes every cut non-arbitrary. The AI is free to look broadly, read the plate, weigh possibilities, go find the manual. What it is not free to do is invent a new name for something the industry already knows how to name.
The standards keep moving, and so do we.
ISO 14224 has been under review, and the ISO 19650 series is mid-revision. Neither our taxonomy nor our variance log is closed either.
An observation that keeps recurring is no longer an exception — it is evidence that a new governed attribute is needed. A taxonomy that stops absorbing new evidence stops being a standard and becomes a legacy asset numbering system: accurate about the world as it used to be.
The point
The reason naming an asset feels like a dark art is that the knowledge has been living in people instead of in structure. This journey has been more about the tactic of getting the data and less about an asset management strategy; TW changes that. Every one of those people was right — that is exactly why you ended up with seven shades of it. And none of it survived their departure.
A structure exists. It has been published, revised, and argued over by standards bodies for decades. What it had never been is assembled — pointed at one asset, in one workflow, at the moment someone is standing in front of the machine. That assembly is the stone.
You take the picture. We do the rest — and now you know what “the rest” is made of.
📱 Download Tag Wizard
UnCommon questions about asset data and asset management
What is an asset taxonomy?
A structured way of classifying equipment so that the same machine gets the same identity every time it is recorded.
A unique identifier for individual assets also helps prevent duplicate entries in asset management and ensures each asset is uniquely identified within the asset management system.
It is not a vocabulary list — it is a stated purpose with words attached, and the purpose is what determines where the classification levels divide.
What is the difference between ISO 14224 and ISO 19650?
ISO 14224 is an equipment taxonomy for reliability and maintenance data collection, originally written for the petroleum and natural gas industries, and it provides a structured approach based on best practices for maintenance management and maintenance operations.
It defines standardized failure modes and causes, supports common terminology across operators and manufacturers, and enables consistent calculation of reliability metrics such as MTBF and MTTR.
ISO 19650 is an information management standard for the built environment, concerned with how information about an asset is defined, delivered, and given status. One governs what a thing is; the other governs what you know about it and how confident you are.
Can AI classify equipment from a photograph?
It can propose a classification. Whether that proposal is reliable depends entirely on whether it is navigating a governed asset taxonomy or generating a name from scratch. Without guardrails, the same asset photographed from two angles can produce two different answers, both plausible.
That matters anywhere asset naming has drifted, because ISO 14224 depends on data quality management and validation processes, and better tracking of failure causes helps reduce downtime.
This article shows how that structure is applied in practice, and how the same logic can be adapted to different industries and business needs without changing the core model.
What is the difference between asset tagging and asset labeling?
Asset labeling is the physical mark — a physical tag fixed to the equipment, carrying an asset name plus a serial number that links the physical asset to the governed record, using a barcode, a QR code, or RFID tags.
A standardized naming system or asset naming convention supports consistent naming across multiple departments and multiple sites.
Tags may also support asset tracking and inventory management, including maintenance schedules on labels where appropriate and GPS trackers for mobile assets or other moveable assets that need location visibility.
Combining the asset’s function with that identifier clarifies identification for specific assets. Asset tagging is the record behind it: the classification, the attributes, and the relationships that make the label mean something.
QR codes can store more data than standard barcodes, while those radio-based tags can be read from several meters away. A label without a governed record is a sticker. Tagged physical assets improve loss prevention and accountability, and they also reduce audit time and human error.
Why do asset hierarchies break?
Most commonly, because location was encoded into the identity. When the tag contains the building, the floor, or the room, moving the equipment invalidates the record.
A naming system or naming convention helps enforce consistency for existing assets and new assets, while asset classifications and a clear naming convention also make tracking assets easier.
Separating where an asset sits from what an asset is (the core lesson of ISO 14224) is what lets an asset hierarchy survive real facilities. Regular audits of the hierarchy help keep parent-child structure accurate over time.
How many levels should an asset taxonomy have?
Nobody has written a good answer to this publicly, and it’s a real question people type. Your answer is honest: as many as the evidence can support, which is why the fourth is optional.
Do I need an asset taxonomy if I already have a CMMS?
This is the objection, and the answer is that a CMMS gives you a container and expects you to supply the structure, straight from the June piece’s argument.
What’s the difference between an asset hierarchy and an asset taxonomy?
Widely confused, rarely explained. Hierarchy is where things sit; taxonomy is what things are. That distinction is ISO 14224’s first principle, and you can own the answer.
Can non-technical staff tag equipment accurately?
Your 11x result answers a question people are genuinely asking, especially with the tech shortage.
How do you handle equipment that doesn’t fit any category? — The eleventh-thing problem. Answering it publicly signals confidence rather than defensiveness.
Tag Wizard ✨ You take one picture. We do the rest.
Very interesting facts, if you were wondering what Nestor is, and why NIST built a parrot?
A short digression, because this one deserves it — and because it shows how long serious people have been working on this problem.
Somewhere in the last decade, enough organizations were losing enough money to unreadable maintenance records that the National Institute of Standards and Technology (the agency that keeps the country’s definition of a kilogram) decided the problem was worth solving.
Not the equipment. The words.
The result is a free, public-domain toolkit called Nestor. It reads maintenance work orders and groups the variants of one idea into a single canonical concept: cmprsr, compressor, comp.
Three spellings, one machine. NIST’s own documentation states the problem plainly: technical shorthand develops fast; “air conditioning unit” becomes “ACU,” and the statistical significance of both is destroyed.
Worse, context decides meaning. Hot obviously matters in an HVAC dataset — but it might mean a room is too hot, which is a problem, or hot water, which is just an object.
The name is the good part. NESTOR stands for Natural Language Extraction of Structured Text and Organization of Records, which is respectable acronym engineering.
But it is also a nod to Nestor notabilis — the kea, the world’s only alpine parrot, native to New Zealand and famous for exactly two things: intelligence, and solving puzzles with tools, often cooperatively.
The parent project at NIST is called KEA, for Knowledge Extraction and Application. Smart bird, smart tools, smart manufacturing. The toolkit, documentation, and source code are at pages.nist.gov/nestor.
This is the part worth sitting with. A federal standards laboratory named a project after a puzzle-solving parrot because the naming problem in maintenance data was bad enough to warrant a decade of research.
Nobody was doing that for fun. And ISO had been working the same ground for years before that, from a different direction entirely.
So when Nestor appears in the table below without a tier of its own, that is deliberate. NIST operates across all four levels rather than at one of them — canonical naming applies wherever a variant can appear, and traceability attaches to the attributes rather than to the classification.
Nestor structures the text after it has been written. We structure the asset before anyone writes about it. Same principle, one layer apart, which is why we published a compatibility statement rather than a competitive comparison.